Loading the page…
Machines on-call for humans
Machines on-call for humans
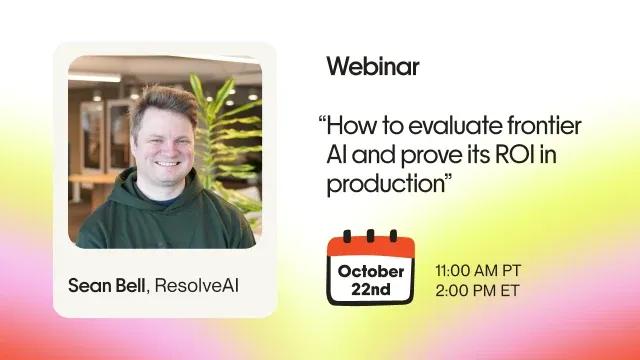
Thu, Oct 2211:00 AM PDT, 30 min
Frontier models keep improving, but a strong benchmark score doesn't show whether a model will hold up in your production environment, or whether it's worth the token spend. For many engineering leaders planning for 2027, the work has moved from just picking a model to evaluating it on real conditions and measuring its full cost and impact to ROI.
In this Tech Talk, Sean Bell, who runs ResolveAI's Applied labs, will walk through his journey and learnings.
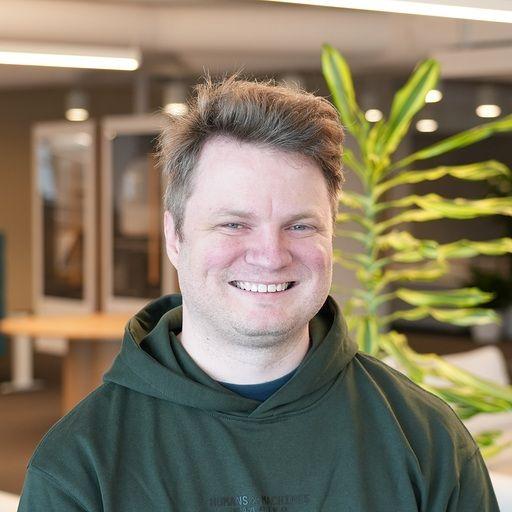
Sean Bell
ResolveAI Labs, previously Director of AI Research, Meta Superintelligence Labs
Know when a domain-specific model beats a general one.
Benchmark on live production incidents, not offline test sets.
Spot early when a cheap in-house build is heading toward a large maintenance bill.
Budget for the full long-term cost of ownership, not just the one-time build.