Loading the page…
Machines on-call for humans
Machines on-call for humans
Finds the cause, weighs the mitigations, and recommends the fastest path to recovery
In the first minutes, ResolveAI pins the incident to
one service, pulls in only its owning team, and
hands them the evidence to fix it
Tests the hypotheses, weighs the
mitigations, confirms the recovery, and
tracks the permanent fix.
Massively parallel reasoning runs each hypothesis against metrics, logs, traces, deploys, and code. Each one is confirmed, ruled out, or traced downstream.
Works the incident in Slack with everyone on it. Takes each question or check, runs it against production, and folds the answer into the investigation.
Compares every way to restore service by time to recover, blast radius, and what it leaves unfixed. Recommends one.
Watches the service after every action and reports back to the channel. Then ties the incident to its root problem and follows the fix until it ships.
The scope is narrowed before anyone is pulled in. Only the owning team joins.
During the incident
One recommended mitigation, ready
to approve. No debate over which fix
to try first.
At recovery
The root problem is tracked until the permanent fix ships.
After the incident
The scope is narrowed first, so fewer people join the call.
72%
faster investigations, with time to root cause under 10 minutes
~60%
reduction in MTTR across production incidents

30%
fewer engineers pulled into each incident
Narrows the scope, finds the cause,
recommends the fix.
Product
Joins when the incident opens and stays until service is restored. Hivemind and the Production graph carry the context.
ResolveAI Labs
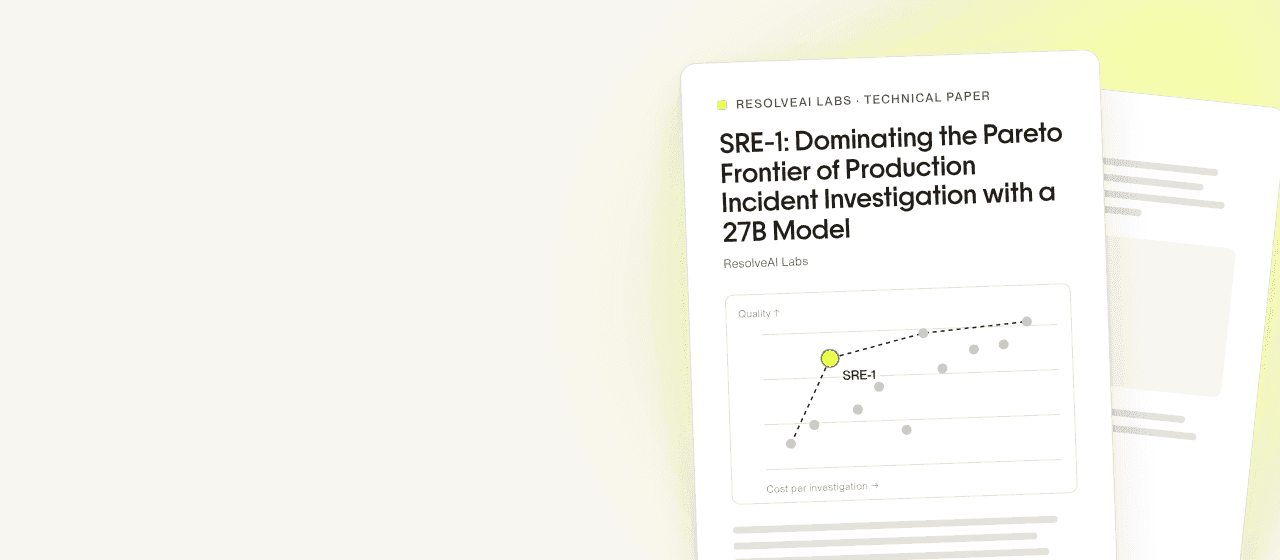
SRE-1 and Massively parallel reasoning test every hypothesis against production before a cause is named.
Security
Scoped autonomy and Platform guardrails: read-only by default, mitigations on your approval, every action logged.
Works within your guardrails.
Your paging, observability, cloud, and code tools, with 60+ integrations.
The cause and the recommended mitigation arrive in your incident channel, terminal, or your own agents.
Every mitigation waits for an engineer. Access is read-only by default, and every action carries an audit trail.
“ResolveAI allowed us to move from hours to minutes for investigations in many incidents. We pull fewer engineers into war rooms, on-call is materially better, and that translates directly to advertiser trust and revenue protection for a billion-dollar ads business.”
Shahrooz Ansari,Sr. Director of Engineering
DoorDash
Investigates with your engineers, identifies the root cause quickly, mitigates and restores service in minutes.